GLM-5.3
Zai-org
Ready

 New
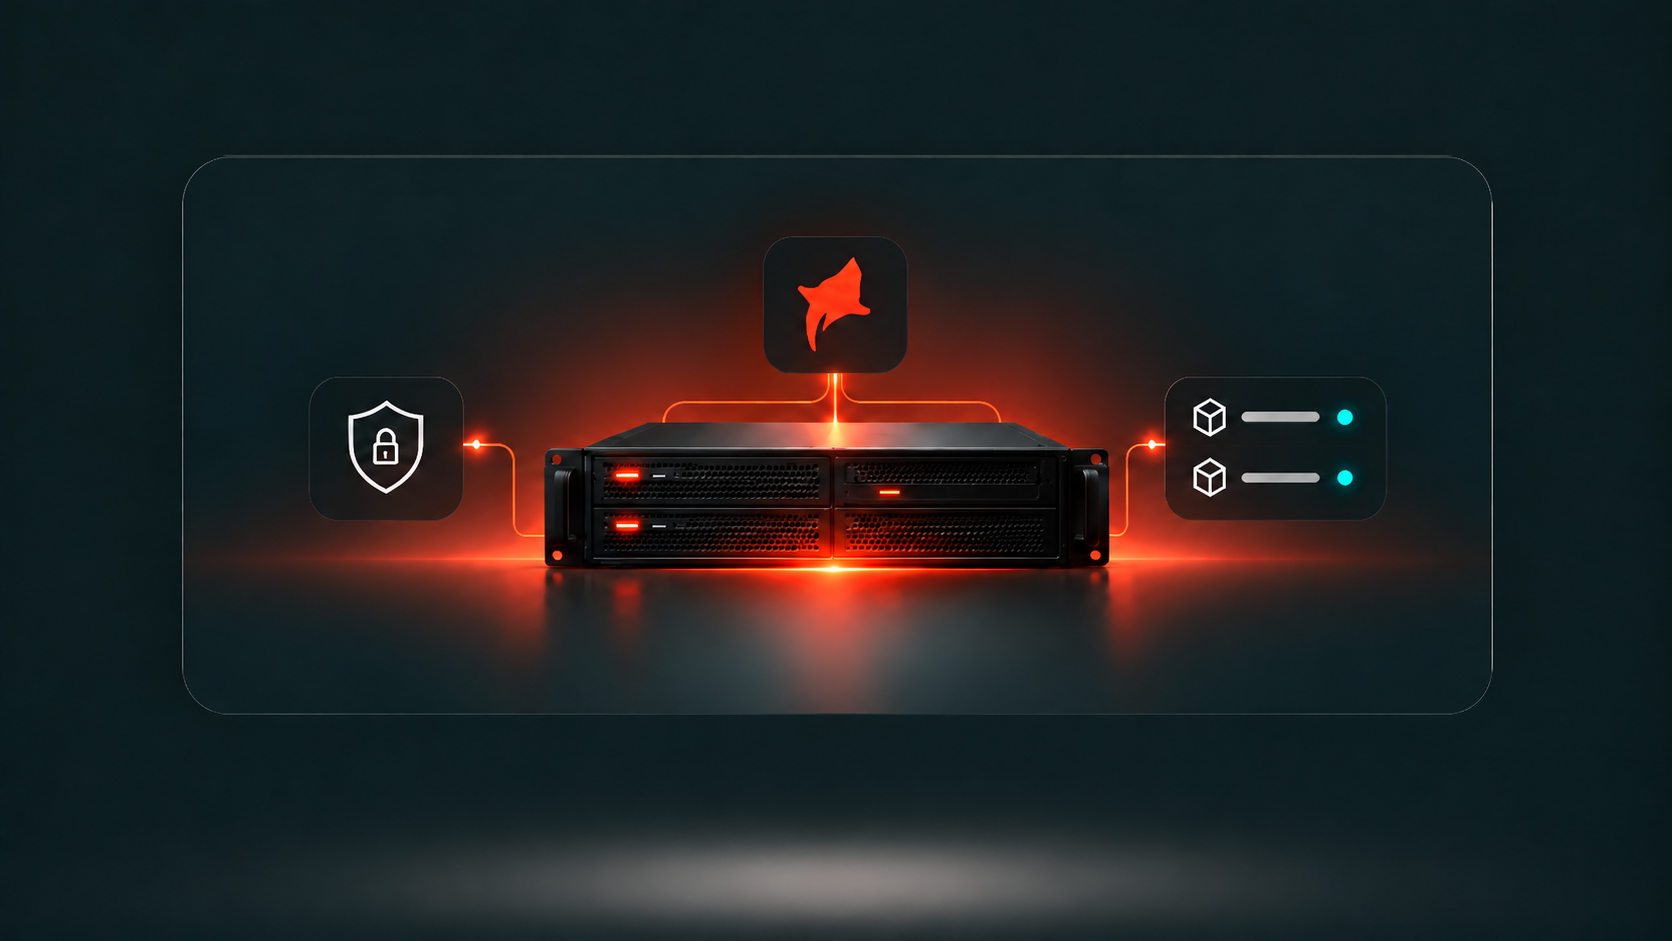
Sovereign AI: private AI infrastructure on hardware you rent or own, fully managed.
Run leading open-source models on one OpenAI-compatible API with zero data retention. Start in our cloud, then move on-prem when you're ready.


GLM-5.3
Zai-org
Ready

Qwen3.6-27B
Qwen
Ready

Gemma-4-31B-it
Ready

100+
years of combined national lab experience

Cloud
to air-gapped, same API

Zero
data retention, by default
Customers

Most business comes down to relationships. Knowing I can call these guys and say ‘here’s what I’m trying to do, what’s going on here, how do we do this?’ - that’s the difference.




The product
Open models used to force a choice: overpay for a closed API, or self-host and run a fleet of GPUs. Now our national lab engineers run them for you, behind one standard API.
How it works
No infrastructure to set up and no migration project - most teams are running their first request the same afternoon.
Step 1
Browse the catalog or try one live in the workbench - no commitment and no credit card required.
Step 2
Swap in the OpenAI-compatible base URL and an API key. Your existing code keeps working as-is.
Step 3
Run it in our cloud, or move the same models and API on-prem when you're ready. Your code stays the same.

Serverless by default
No clusters to provision and no scaling to monitor. Send a request and capacity is there; send millions and it still is.

One API, every model
Leading open-source models sit behind a single OpenAI-compatible endpoint. Switch models by changing a string, not your stack.

Run by our engineers
National lab engineers run the infrastructure, so your team never gets paged about a GPU.

Built for teams
Bring your whole team onto one organization - a shared token pool, one consolidated invoice, per-member and per-project spend caps, and role-based access with scoped API keys. Set the budget once and let the team build inside it.
NOT JUST FAST
Every inference provider is fast - throughput and latency are the price of entry. What sets Hoonify apart is everything around the token: a price you can see up front, data that's never retained, and one API that runs the same from your first prototype to your own air-gapped hardware - without changing a line of code.
Every rate is published per million tokens, right next to the model - no "contact us" to learn what you'll pay, no surge, no idle GPU-tax, no per-seat math. You see the number before you turn the key.
Nothing is retained after a request and we never train on your prompts. Privacy is the default, not an enterprise upsell.
Start serverless in minutes. When a workload needs it, run the same models and API on your own hardware, on-prem or air-gapped.
BUILT FOR BUILDERS
The whole car is only useful if you can drive it on day one. Hoonify is OpenAI-compatible from the first call - if your app already talks to a closed API, it already talks to Hoonify. Point your existing SDK at our endpoint, drop in a key, and every model on the network is available through the same calls you already wrote.

Drop-in compatible
Works with the OpenAI SDKs, LangChain, LlamaIndex, and the tools your team already uses. Streaming, function calling, and structured outputs included.
Try it in the workbench
Run any model live in the browser before you write a line of code - compare answers, and copy the request straight into your app.
Swap models freely
Route different jobs to different models from the same setup. Test a new release against production traffic without a rewrite.
One key, full catalog
A single API key unlocks every model on the network. No per-model onboarding, no separate accounts, no waitlists.
Same SDK. Same code. One new base URL.
PAY PER TOKEN
Per-million-token pricing, billed for exactly what you send - no surge, no seats, no reserved capacity, and no idle GPU-tax. You pay for tokens, not for hardware sitting warm between requests, so there are no surprises at the end of the month.

MONTHLY TOKENS: 100M
MONEY SPENT: $40
MONTHLY TOKENS: 100M
MONEY SPENT: $1600


blended in/out rate · taxes excluded
Transparent rates
Every model lists its in and out price per million tokens, up front. What you see in the catalog is what lands on the invoice.

No idle GPU-tax
You're billed per token, never per GPU-hour. Reserved capacity and self-hosting make you pay for silicon whether it's working or idle - here, capacity you're not using costs you nothing.

No surge pricing
Rates don't spike with demand or time of day. Budget once and it holds, whether you send a thousand tokens or a billion.

$10 in credits free
Every account starts with $10 in credits and no credit card. Enough to run your real prompts and see the numbers before you spend a cent.


PROBLEM IN, SOLUTION OUT
A model that streams a few milliseconds quicker doesn't matter if it takes a quarter to wire up, a contract to switch, or a budget review to scale. Hoonify collapses the distance between a problem and a working answer: try a model the moment you have an idea, ship it the same afternoon, and change your mind as often as the problem does - without a migration, a rewrite, or a sales call.

Idea to first call in minutes
Prototype in the workbench, then move the same request into production behind one base URL. No infrastructure stands between you and a working solution.

Iterate at the speed of the problem
Swap models, tune prompts, and re-run against real traffic in the same setup. When the problem shifts - or a better model lands. You adapt in a config change, not a project.

Solve the workloads you'd shelved
The jobs that were too expensive or too sensitive to ship on a closed API - high volume, proprietary data, always-on - become the easy ones. The bottleneck stops being cost or infrastructure and goes back to being your idea.

Outcomes, not overhead
No GPUs to stand up, no capacity to forecast, no on-call rotation. Our engineers handle it.
Proof in production
One platform powers every team - start with the model that fits the job, and switch anytime without changing your setup.
Create your account-68%
lower inference spend
after moving everyday workloads from a closed API to Hoonify.
I've been testing Hoonify’s inference through our harness while working on the above, and it’s been insanely fast. I'm wicked impressed. Great work team.

TRUST & PRIVACY
Zero data retention
Nothing kept after a request completes
Never trained on your data
Your prompt and outputs stay yours
Open weights, no vendor lock-in
Standard API and open models mean you can switch or leave anytime, code intact
Ready to bring it in-house?
Run the same models on-prem or air-gapped with Sovereign AI, fully managed by our engineers.
BUILT TO NOT FAIL
Hoonify Inference runs on TurbOS® - the compute platform built for national labs, scientific computing, and mission-critical systems. That same operational discipline routes every request you send, so latency stays low and capacity scales under you without a page to your team.
Intelligent request routing and model-weight caching put your call on warm capacity fast - streaming tokens back in milliseconds, not seconds.
GPU scheduling scales from your first request to peak volume automatically. No capacity planning, no reserved instances, no idle spend.
Provisioning, scaling, and on-call are ours, not yours. Your team ships product instead of babysitting a GPU fleet.
What teams build
Start with the model that fits the job and switch anytime without changing your setup.
Give every team a private AI assistant they'll actually use, so sensitive work stays on systems you control.
Runs great on GLM

Retrieval-augmented generation (RAG) turns your own documents and data into instant, accurate answers, reliable enough to put in front of customers.
Runs great on GLM-5.2.

Review code, draft tests, and explain unfamiliar services right inside your stack - on models you control
Runs great on Qwen Coder.

Tag, route, and structure high-volume records end to end - the always-on jobs that were too expensive to run on a closed API.
Runs great on Gemma 4.

Build agents that plan and use your tools across long tasks - with checkpoints wherever you want a human to sign off.
Runs great on Inkling Small.
Train an open model on a few hundred of your own examples, so it learns your formats and your edge cases instead of guessing at them.
Runs great on Qwen 3.6

Get Started
Start building in minutes with $10 in credits free - point your SDK at one base URL and every open model is a request away. Or have our team map the right models and expected savings for your workloads.
Need it on your own hardware? Talk to an expert.
Loading form…
No spam. We use this only to follow up about your workloads.